BiDex-100
Overview Document Setup Domain Randomization Tasks Leaderboard News

BiDex-100

A Comprehensive Benchmark for Bimanual Dexterous Manipulation Across 100+ Simulation Tasks

Anonymous Authors

Anonymous Institution(s) · Submitted for review

Video

Project showcase.

Abstract

Benchmarking bimanual dexterous manipulation along capability edges.

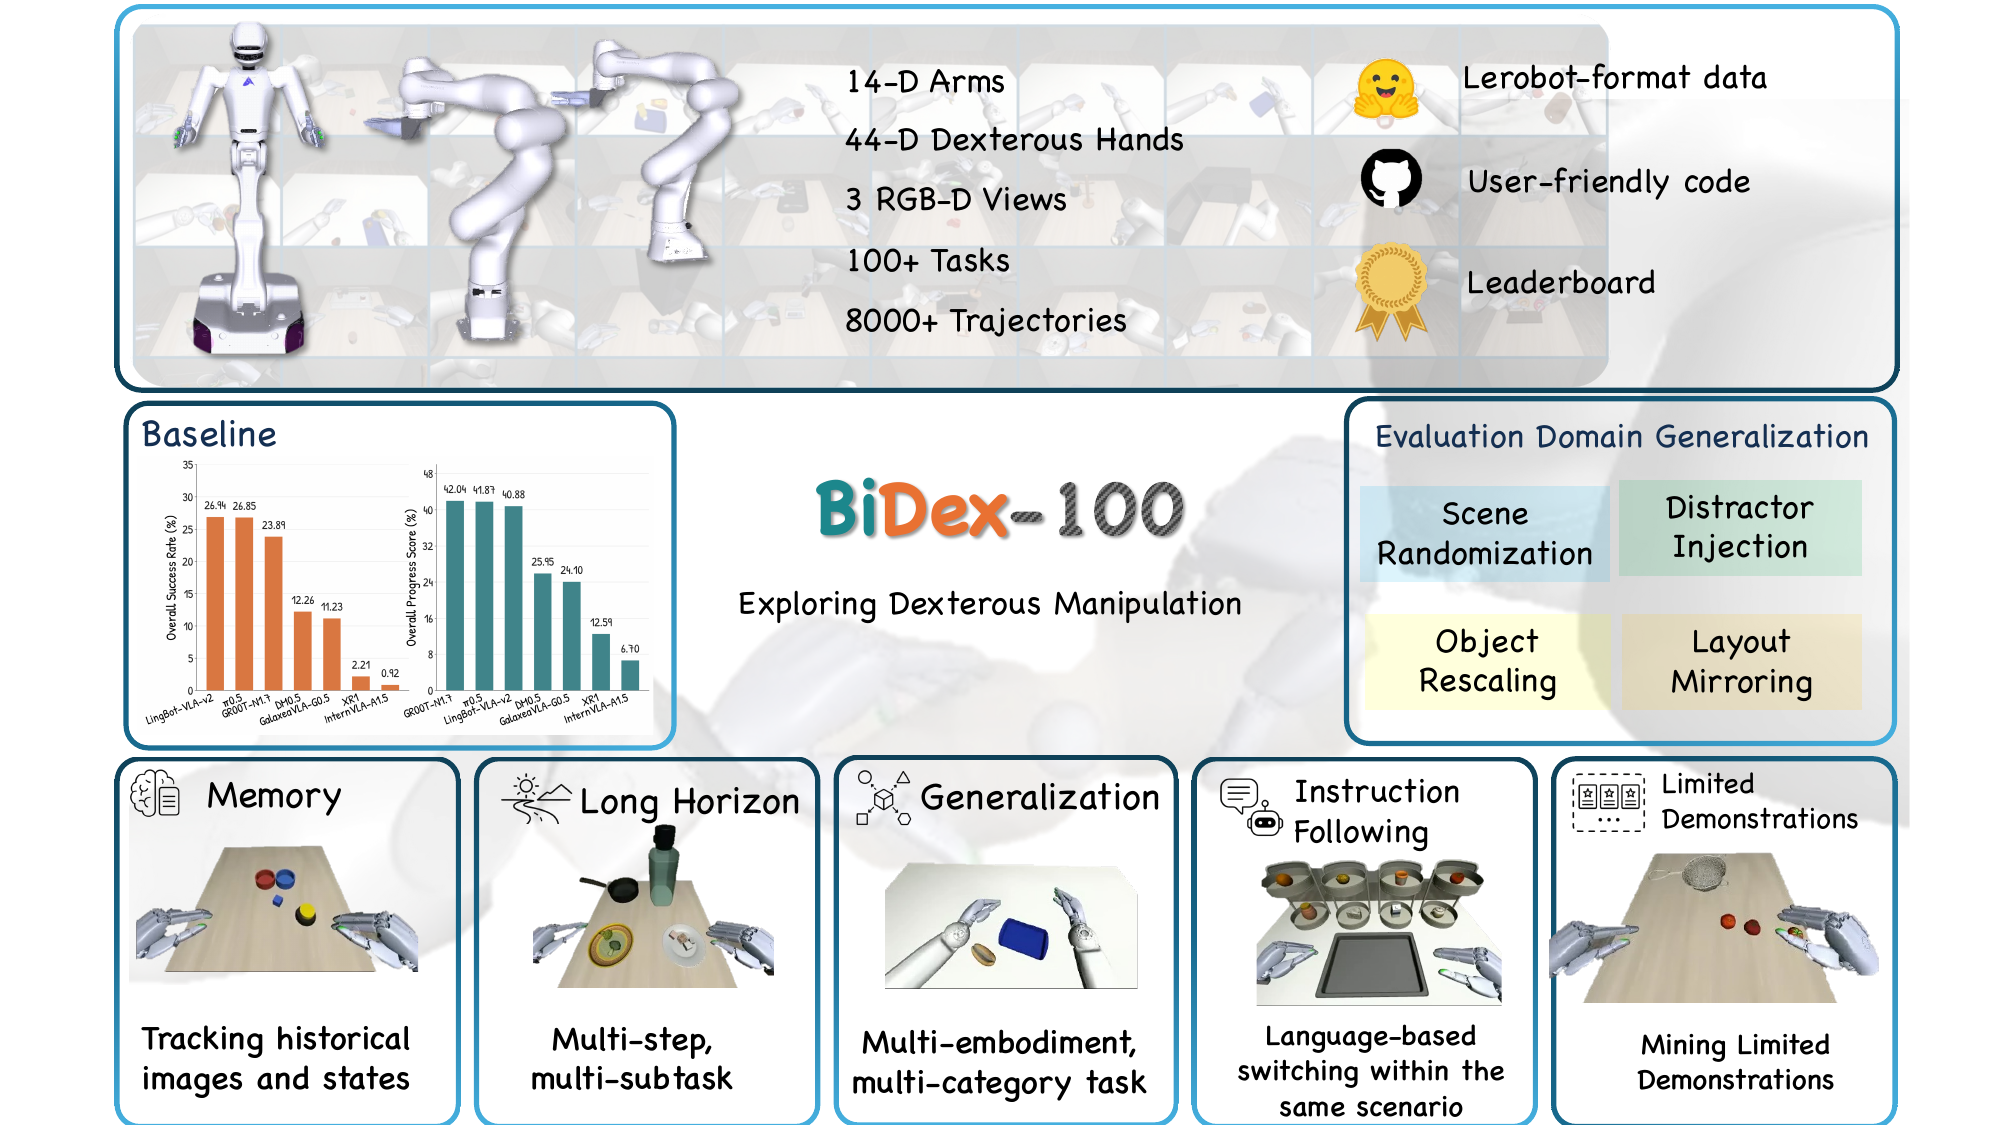
Bimanual manipulation with dexterous hands has attracted growing attention in research on robotic action models. However, few studies have developed benchmarks specifically tailored for dexterous manipulation, leaving it unclear how the dexterous-manipulation capability of existing models actually bears out. We present BiDex-100, a simulation benchmark for bimanual dexterous manipulation that combines broad task coverage, multi-dimensional evaluation, and high-DoF hand embodiments. Concretely, the benchmark comprises 106 tasks organized along five capability axes: Generalization, Instruction Following, Limited Demonstrations, Long Horizon, and Memory. Each task is paired with an out-of-domain variant featuring controlled visual and spatial changes, allowing systematic assessment of robustness. In addition, the benchmark supports two embodiments and provides 8,080 success-validated teleoperated demonstrations, totaling 6.25M frames. We evaluate seven recent Vision-Language-Action models under a unified protocol, establishing baselines for capability-specific performance, robustness, and data efficiency. Code, tasks, data, and evaluation tools will be made public.
System Overview

106 declarative tasks, two bimanual dexterous embodiments, matched ID / OOD scoring.

BiDex-100 overview: 106 tasks across five capability axes, two bimanual 22-DoF dexterous embodiments, 8,080 demonstrations, and matched In-Domain / Out-of-Domain evaluation with progress-based scoring.
Overview of BiDex-100. The benchmark provides 106 declarative task specifications across five capability axes, 8,080 success-validated teleoperated demonstrations on two bimanual embodiments equipped with dexterous hands, and progress-based scoring under matched In-Domain and Out-of-Domain protocols. Five representative tasks, one per capability axis — Memory, Long-Horizon, Instruction-Following, Limited-Demonstrations, and Generalization — each shown with a real demonstration and its language instruction.

Setup

Embodiments, teleoperation pipeline, and synchronized observations.

Embodiment & Observation

Two bimanual 22-DoF dexterous embodiments, one 58-DoF joint interface.

Both platforms share the same 22-DoF Shadow-style dexterous hand on two 7-DoF arms, giving a 58-DoF action space. Observations are synchronized RGB-D images from head, left-wrist, and right-wrist cameras at 480×360 and 25 Hz, with full proprioceptive state. All 106 tasks are evaluated on the dual-Franka platform; 10 Generalization tasks are additionally instantiated on the Astribot S1 humanoid.

Teleoperation Pipeline

From human hands to bimanual dexterity — 8,080 validated episodes.

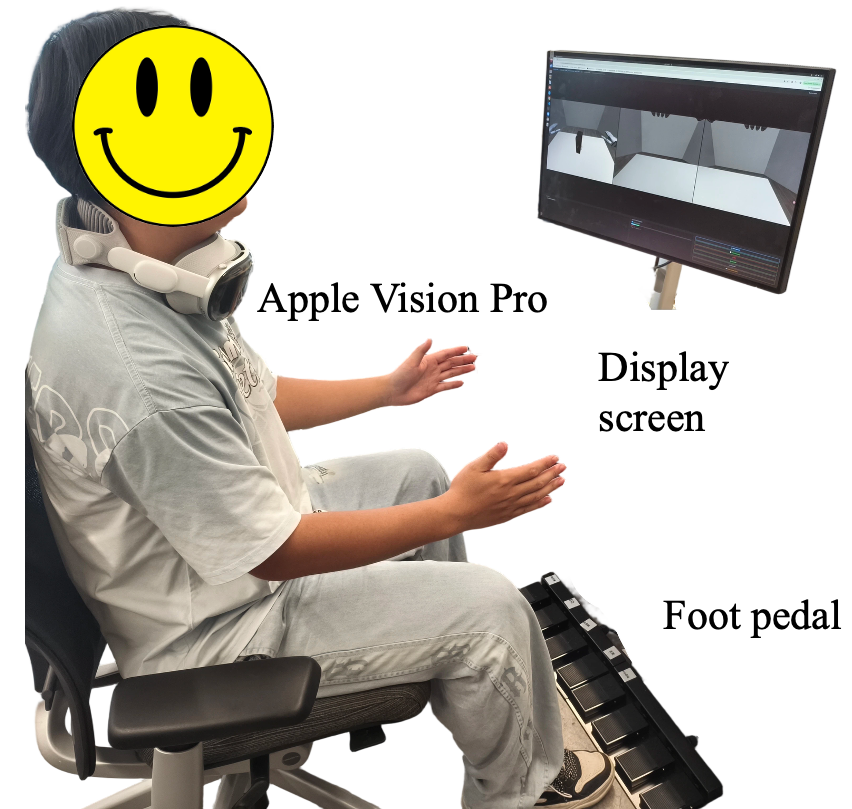
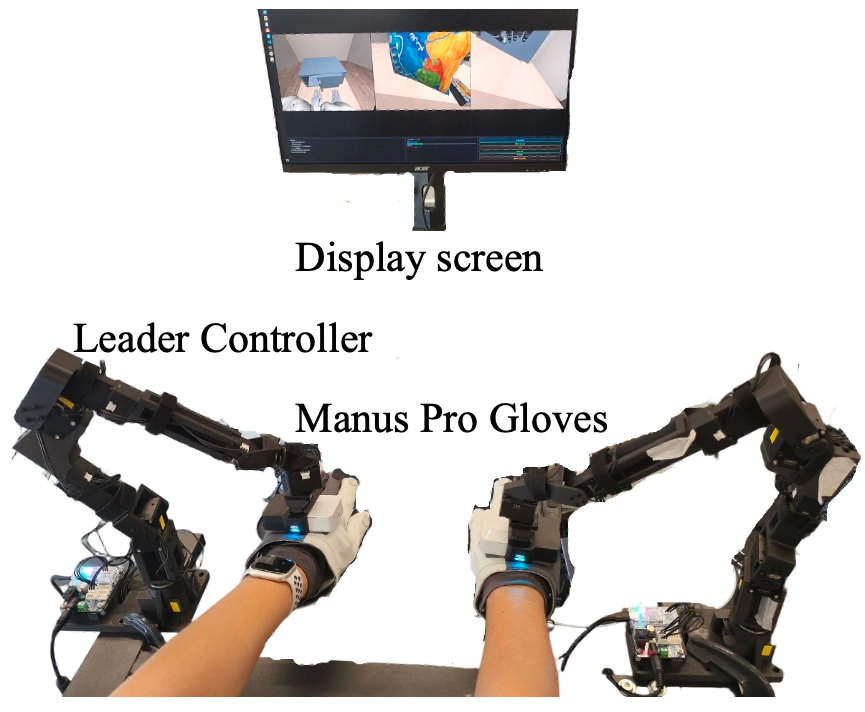
Demonstrations are collected through two complementary teleoperation modalities — an exoskeleton glove and an Apple Vision Pro headset — that feed a single optimization-based retargeting stack, producing one homogeneous 58-DoF data stream across platforms and devices.

Exoskeleton glove: joint-level finger tracking teleoperation pipeline used in BiDex-100

Exoskeleton glove

An exoskeleton glove streams joint-level finger tracking for high-dexterity, contact-rich manipulation.

Apple Vision Pro WebXR teleoperation pipeline used in BiDex-100

Apple Vision Pro

An Apple Vision Pro headset (WebXR) streams wrist poses and 25 hand keypoints for untethered operation.

Capture wrist & hand motion

The glove or headset streams human hand keypoints and wrist pose at the control rate; a fixed linear node map converts headset keypoints to the glove's canonical joint representation.

Retarget & solve IK

Arm targets come from a constrained NLP over the first five joints (SLSQP) minimizing weighted position, orientation and temporal-smoothness cost; two wrist DoF and arm-length mismatch are recovered in closed form. Hand targets are a weighted least-squares fit of robot keypoints to tracked human keypoints.

Record actions, states & observations

Each step stores the 58-DoF action, 130-D observation, six RGB-D streams, subtask-progress annotations, and a serialized initial state enabling exact replay of the episode's initial conditions.

Six Synchronized Camera Views

One episode, six time-aligned RGB-D streams.

Every demonstration episode stores color and depth for the head and both wrist cameras, fully synchronized. Press play to watch all six views in lockstep; drag the timeline to scrub. (Demo: Pour Ice Between Two Cups · Dual Franka.)

0:00 / 0:00 Pour Ice Between Two Cups · Dual Franka

Dataset

A closer look at the demonstrations.

Explore how tasks, demonstrations and recorded time are distributed across the five capability axes and two embodiments.

8,080 demonstrations6,248,973 frames69.43 h recorded at 25 Hz

01 / Embodiment → capability → task → duration

Where demonstrations come from

106 tasks · 8,080 demonstrations

Each fine ribbon represents one task. Filter a capability to reveal task names, or select a task to trace its full path. Duration bands use each task's mean demonstration length.

Swipe horizontally to explore all four stages →

Trace an individual taskHover or focus to inspect a task.

Hover or focus on a flow to explore its demonstrations.

02 / Composition

Five axes, different shares

Select an axis to see its share of the dataset.

03 / Recorded time

The scale of each capability

Hours

One timeline per demonstration, across all synchronized views.

Statistics use the full LeRobot v2.1 metadata across all 106 tasks. Recorded time = frames ÷ 25 Hz; synchronized camera views are counted once. Download per-task statistics ↗

Domain Randomization

Matched In-Domain / Out-of-Domain evaluation through controlled randomization.

Goals are machine-checkable predicate conjunctions with deterministic seeding and matched In-Domain / Out-of-Domain variants. Strict success requires a perfect 100; the following progress score rewards partial completion in [0,100]. Below, each randomized condition is demonstrated from the head camera on a different out-of-domain task.

01
Success & progress
Strict success requires all predicates; the following score sums latched weighted subtask credit (Σ wₖ = 100) to expose partial progress.
02
Latched & ordered credit
Must-hold, latch-violation and ordered-subtask mechanisms defeat touch-and-go, forbidden outcomes and out-of-sequence gains.
03
Matched ID / OOD
Every task has one baked __ood variant (identical seed & initial state) over five scripted shifts — directly comparable robustness.
04
Data efficiency
The Limited-Demonstrations axis isolates a fixed 30-demonstration regime, measuring skill acquisition when training data are scarce.

Five domain-randomization modes

The five scripted out-of-domain shifts

Scene randomizationFloor, wall and tabletop textures redrawn from a held-out pool, with lighting position and intensity jitter.
Region offsetPlacement regions translated 4–9 cm in the world frame (precision-critical slots excluded).
Distractor injection2–6 sibling objects added; grasping a distractor terminates the episode at its latched score.
Object rescalingArticulated objects scaled by {0.85, 0.9, 1.1, 1.15}.
Left-right mirroringThe whole layout is mirrored about the workspace midline; left/right is swapped in the instruction.

Tasks

The 106-task capability atlas.

Each card shows a head-camera frame from a real demonstration, the task's per-subtask completion (mini bars), and the best-performing model. Click any card for the demo replay, full per-subtask completion rates, and the 7-model In-Domain / Out-of-Domain breakdown. Filter by capability axis below.

Compare the baselines

From demonstrations to evaluation.

Explore seven VLA models across all 106 tasks, with matched ID and OOD results.

Explore the leaderboard